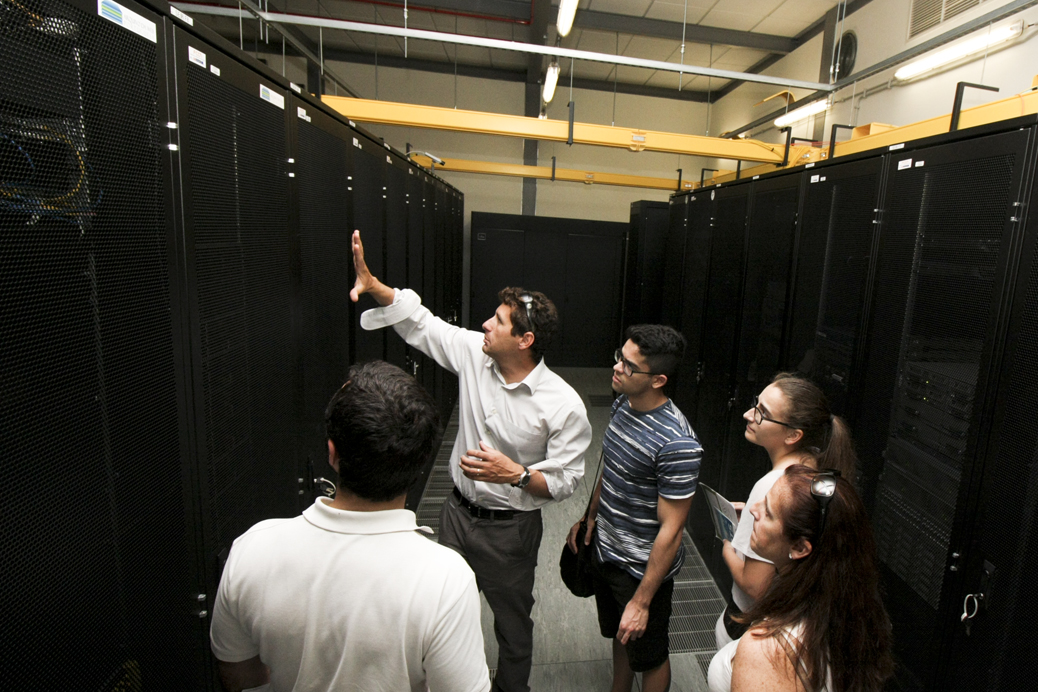
The research and education community has been requesting the bulk download of web-archived data and index files (CDXJ), for instance, to feed AI training models, optimize routing of web archive requests or recover information from selected websites (e.g. news). Arquivo.pt begun making all its CDXJ index files publicly available in real-time to facilitate the bulk […]
The Programming Historian aims to develop digital skills among the Humanities researchers through the publication of practical lessons in several languages. The call Computational analysis skills for large-scale humanities data originated 7 new lessons. One of them was the tutorial "Timeline summarization for large-scale past-web events with Python: the case of Arquivo.pt" developed by Daniel […]
Arquivo.pt launched a new version named Dionisius, on March 24th 2021. 1.8 billion images from the past Web are now searchable on Arquivo.pt. Supporting large-scale image search over Web archives is a world-wide innovation. To learn more about the development of this system, watch the video "Arquivo.pt image search 2020-2021". Try for example, how a […]